Key Takeaways
- Enterprise trust in AI runs directly through the quality and governance of the data feeding it, and that realisation is now widespread.
- Most organisations sense a context gap: data that exists but lacks the meaning, enrichment, and consistency that AI systems need to act reliably on it.
- Location intelligence remains a meaningful, underused edge, even as every vendor converges on the same broad messaging.
Every year, Big Data London is a good temperature check. Not just for what the vendors are pitching, but for what practitioners are wrestling with every day. This year was no different. I spent two days presenting, talking to customers and peers, and listening. A few things came through clearly.
The AI conversation is shifting from “What can it do?” to “Can we trust it?”
The most consistent theme I heard was trust, and not in an abstract sense. People want to know: how do I know my AI is making the right call? That question came up in almost every conversation I had, regardless of industry and role.
What struck me is that most people have already connected the answer back to data. A year ago, you might have heard more hand-wringing about the models themselves. This time around, the realisation was settling in: the AI is only going to be as good as the data you feed it. You can’t trust the output if you can’t trust the input.
This tells me the conversation is moving to the right place.
Why is governance suddenly everyone’s favorite word?
Data governance was everywhere at Big Data London this year, and not in the typical compliance sense. People are talking about governance as the mechanism that makes AI trustworthy at scale: consistent definitions, clear lineage, rules that travel with the data across systems.
The energy around this felt genuinely new. For a long time, governance was the thing organisations said they’d get to “eventually.”
Now that AI systems are acting autonomously on data, the stakes of skipping it are visible in a way they weren’t before. A model that runs on inconsistent, ungoverned data produces a wrong report and it takes a wrong action. That’s a different kind of problem.
What is the context gap, and why does it matter for AI?
One theme I heard repeatedly is something I think about a lot in my own work: companies feel like their data suppliers aren’t helping them manage the context layer.
When an AI system tries to reason about your data, it needs meaning:
- What does this attribute represent?
- Where did this record come from?
- Is this address reliable enough to route a decision on?
That semantic and contextual richness is core to what makes data ready for AI.
This is where data enrichment becomes critical. Data that arrives with pre-linked context, verified attributes, and real-world grounding gives AI systems the complete picture they need. Without it, you’re asking models to reason with incomplete information. They’ll give you an answer, but you won’t always be able to trust it.
What role does location intelligence play in AI?
Of everything I talked about in my speaking session, the location data thread sparked the longest follow-up conversations. There was a lot of interest in how location intelligence can add a competitive edge: connecting records, enriching customer profiles, grounding AI decisions in physical reality, and identifying risk.
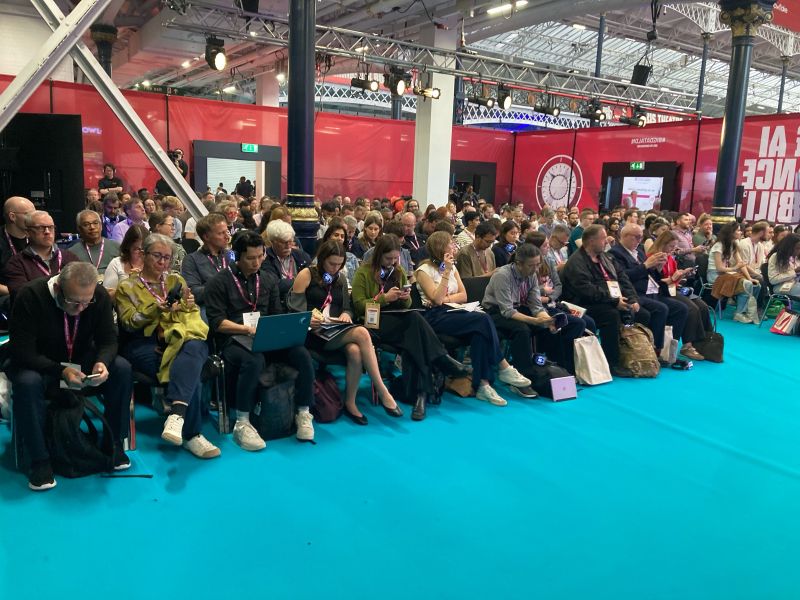
A full house at my Big Data London session, AI Doesn’t Know When It’s Wrong: Here’s How You Can. The questions about location and AI kept coming.
That appetite made sense to me. Location intelligence is one of the most effective ways to give AI systems a complete picture of the entities they’re reasoning about. Without it, you’re working from internal data that often lacks the physical-world context needed to make a decision you can stand behind. With it, you get accuracy, explainability, and an advantage that most organizations are still underusing.
That capability is deep and built into how Precisely thinks about data. If AI systems are going to reason about the world, they need data that’s anchored to the world. That’s increasingly the thing that separates accurate AI outputs from confident wrong ones.
What are organisations going to do with all these AI agents?
Agents came up constantly. What I found useful were the honest questions underneath: what problem does this agent solve? What happens when it’s wrong?
That second question is where bias came up more than I expected. People are acutely aware that AI systems can amplify bad assumptions embedded in the data. External data, used well, is one of the most effective tools for reducing that risk. Diverse, high-quality enrichment data adds context that internal data alone often can’t supply. But it has to be managed carefully, with clear lineage and real governance behind it. Otherwise you’re just moving the bias problem further upstream.
What can you do to get your data AI-ready today?
The conversations I had at Big Data London reinforced something I believe about where we are right now: the organisations that will get the most value from AI are treating data readiness as a strategic priority, right now.
The models are ready and the infrastructure is maturing, but the biggest obstacle most enterprises face is the data foundation.
The good news is that Precisely has built something to help you meet this moment and overcome your biggest data challenges. I encourage you to join us for Precisely Now, our virtual event on October 8, where we’ll reveal the latest insights and tools you need to take the next step toward AI-ready data today.
VIRTUAL EVENT
Precisely Now | See what we’ve built for this moment
Join us live on October 8th for a one-hour event unveiling our new unified data management platform, AI builder experience, and a conversation on what enterprise AI actually takes to deliver.